Why a Consistent AI Character Changes With Every Outfit
Why does a consistent AI character look different in every outfit with the same LoRA? Outfit changes can pull the face away from the character. I'm Labo, the lighthouse keeper. Today's page is about the day my trained LoRA drew the same character, but she looked like a different person in every outfit, and the full-body shots fell apart too. If you want a consistent character across panels, this is the wall. My guess from that day: change the outfit, and the AI stops seeing the same person.
She only changed clothes, and somehow she became a stranger.
The student came in looking pleased. Her dad draws webtoons and never gets a day off, so she's learning to draw manga with AI at home and take a few tired steps off his hands.
"The LoRA finally works. Can I make the same character now?"
Student: Labo, last time you fixed the epoch 4 and 6 thing. Back to txt2img, ControlNet holding the shape. So now I just attach the LoRA and draw, right?
Labo: That was my mood too. With the LoRA really working, I thought all that was left was to draw. Same second style LoRA. Quick recap:
- Trained on an RTX 4090 rented on RunPod
- 55 images × 5 repeats × 10 epochs = 2,750 steps
- Captions cross-checked by Claude and ChatGPT, about 95% accurate
- Epoch files 1 to 9 plus the final one. Epoch 5 was the best, and I used 6 as well
Student: Way more prep than your first one.
Labo: My first RunPod LoRA was 36 images; this one was 55, with two AIs on the captions. On June 7 I drew with it properly.
"Close-ups worked. What about full-body shots?"
Student: And? Did it work this time?
Labo: Half of it. The close-ups had the style. When a face fills the frame, the style I'd taught came through.
Student: Finally! And the other half?
Labo: The full-body shots failed, both times. The ones that show her from head to toe.
Student: Is that so different? It's the same person.
Labo: What the AI has to draw changes with the size of the shot. In a close-up, the face, hair and eyes are most of the picture. In a full-body shot you add shoulders, arms, hands, waist, legs, feet and every fold of the clothes. The more there is to draw, the more it shows what the training really taught.
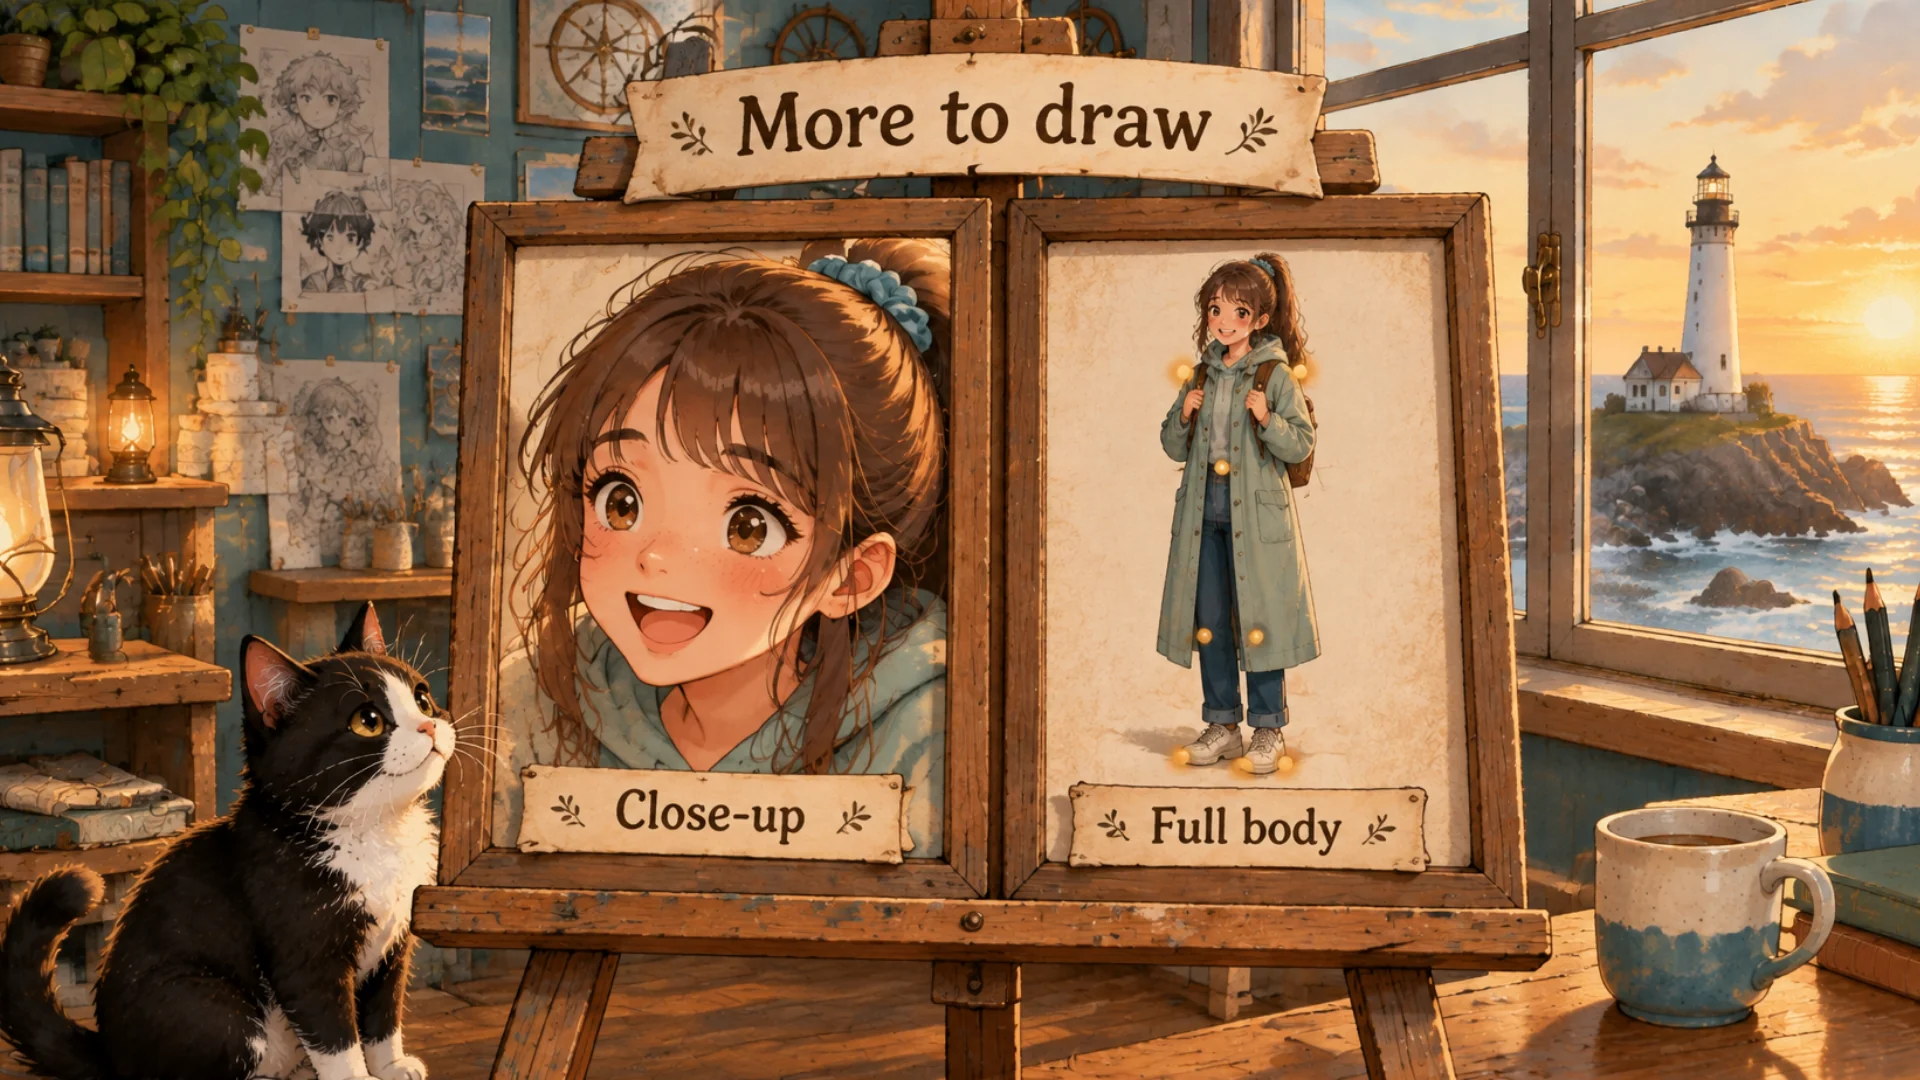
The same woman, close and far. The full-body frame asks for much more.
Student: So how did the full-body ones go wrong?
Labo: Two ways.
- The same woman in different outfits wasn't seen as one person. Every time the clothes changed, she came out like someone else.
- The body didn't come out right either. In the full-body shots, the figure didn't hold its proper shape.
"Why is 'the same person' so hard for an AI?"
Student: That's strange. Webtoon heroes change clothes every episode, and readers still know it's them.
Labo: People do. We look at the face, the hair, the build, the way someone stands, and think, "Oh, it's her." The clothes are just clothes. But the AI doesn't start out knowing "this is the same person, only the outfit changed." It looks at 55 images and bundles whatever often shows up together.
Student: So if every outfit is different...
Labo: This part is my guess, not proven. I think the outfits were so varied that it never learned the body. If every image has different clothes, the shape underneath is hidden by different fabric every time. A long coat in one, something short in another. From the AI's side, it rarely got a clear look at "this is how her body is built."
Student: So that's why the body broke and she didn't look like one person?
Labo: I think both came from the same root. It didn't learn the body, so the body broke in full-body shots. And with no shared body to hold on to, she became someone new with each outfit. Still, it taught me one thing: to me, the "same person" that's obvious to any human is the hardest thing for an AI.
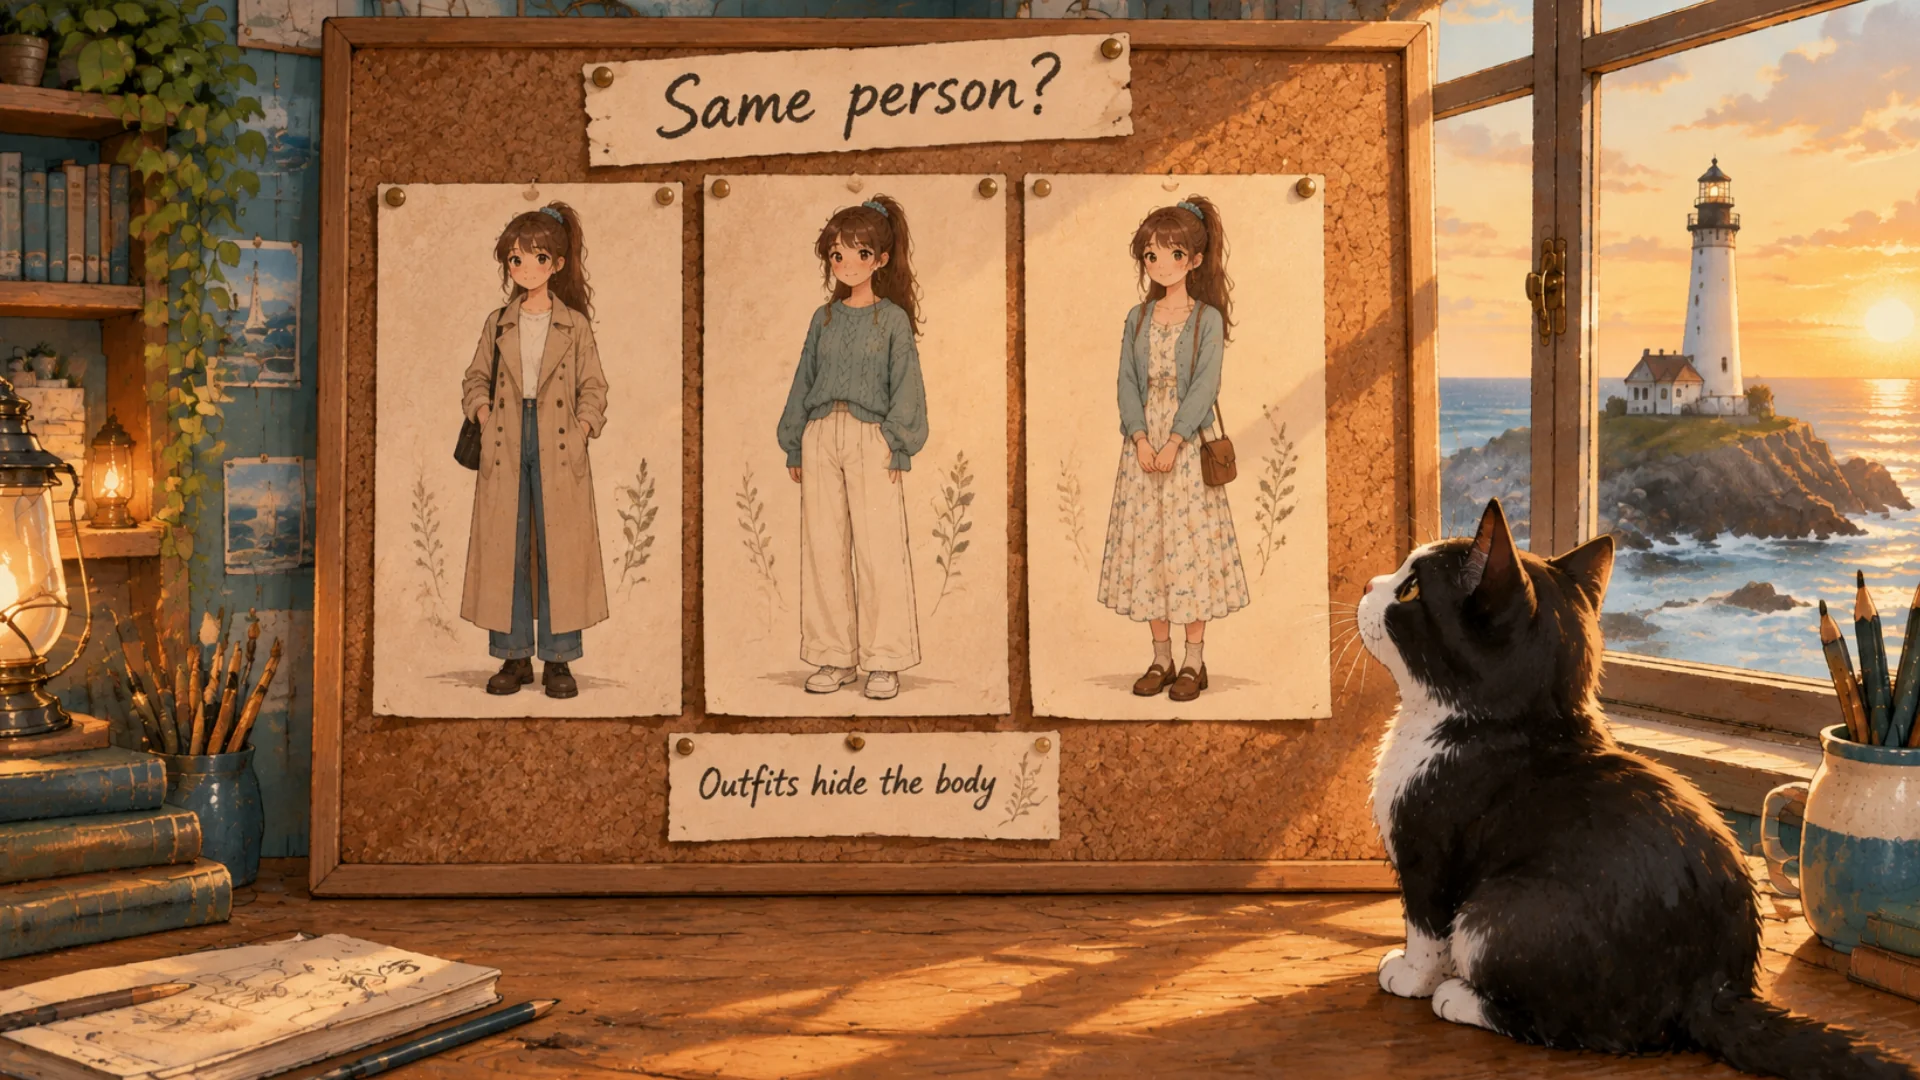
One person to our eyes. To the AI, the clothes cover her differently every time.
"What was inside the 55 images?"
Student: Were all 55 pictures of her?
Labo: No. Going by the file names, a lot of them were scenes with two or three people, and background pictures.
Student: Wait, isn't that like your first LoRA? You put in a whole artwork and the AI didn't know what to learn.
Labo: You remembered. The lesson then was "don't pick the best images, pick images where only the thing you're teaching shows." These 55 were chosen far better, but group shots and backgrounds were still common. How much that added to the failure, I don't know. The biggest thing I saw was the outfits.
Student: Then what should I look at when I pick my dad's drawings?
Labo: From my own runs, count these three once:
- How many people are in each image
- Whether it's only a background, with no one in it
- How different the outfits are between images of the same person
"So how do you teach the body?"
Student: If the clothes kept it from learning the body, then take the clothes out of the equation?
Labo: That's where my thinking went too. Don't teach the style and the shape of the body in one bundle. Split them.
Student: Teach the body separately?
Labo: Separately. That's next time: a separate body dataset, taught like figure drawing. And that one is working well.
FAQ
Q. My LoRA makes the same character look like a different person in each outfit. Why?
In my case the outfits in the training images were very varied. I think the clothes hid the body, so it never learned it. Afterwards I taught the body's structure with a separate set.
Q. Close-ups look great but full-body shots fall apart. Is that normal?
It happened to me: the close-ups had the style, and the full-body shots failed both times. A full-body shot has to draw the whole figure, so it shows whether the body was really learned.
Q. Can I put group scenes and backgrounds in my training images?
My 55 had plenty of both mixed in. When you pick, count the people in each image and check whether it's only a background.
What the artist did: picked 55 images, chose epochs 5 and 6, sorted "close-ups work, full body failed twice," and guessed the outfits were too varied.
What the AI did: Claude and ChatGPT cross-checked the 55 captions (about 95% accurate); an RTX 4090 ran 2,750 steps; the LoRA drew the pictures.
Official pages: ComfyUI on GitHub and Kohya_ss on GitHub (both open source, free; GitHub shares code in the open, so anyone can see what's inside before running it), RunPod (paid by the hour, see the site for prices), Claude (Anthropic), ChatGPT (OpenAI).
Written October 2026 from Labo's own records. The cause is my guess from the results, not a proven conclusion. Program screens and versions may change. The original Korean post: 로라 학습, 같은 캐릭터가 왜 다른 사람처럼 나와요? (Korean)
Lighthouse log. A ship that changes its sails is still the same ship. Obvious to any sailor, and, I think, the hardest thing for an AI to learn.
Keep reading
- Previous post: LoRA Epoch 4 vs Epoch 6 Look the Same? img2img vs txt2img
- More on LoRA · AI art
- All posts in Draw Manga with AI at Home


Comments
Post a Comment